Infrastructure

Building a Minimal HAProxy Load Balancer on Rocky Linux 10

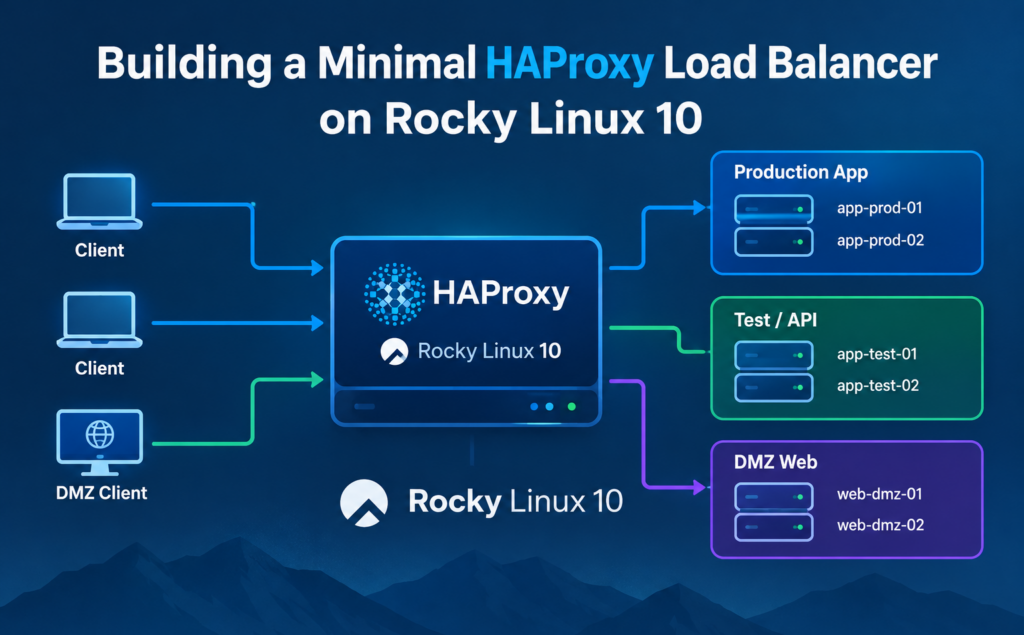
A practical guide to building a small, hardened HAProxy load balancer on Rocky Linux 10 using Layer 4 TCP load balancing, TLS passthrough, multiple frontends and a separate DMZ interface. HAProxy is one of those tools that can look intimidating when you first open the configuration file. In reality, a basic Layer 4 load balancer can be surprisingly small and lightweight. I recently built a small, production-style HAProxy load balancer on a minimal Rocky Linux 10 installation. The server fronts several applications, including an application hosted in a DMZ, and passes HTTPS traffic through to the backend servers without terminating TLS. That last point is important. The HAProxy server doesn’t hold any certificates and doesn’t decrypt the application traffic. It simply accepts the TCP connection, selects a healthy backend and forwards the encrypted connection to it. TLS remains between the client and the application server. This guide documents the build from start to finish, including the networking, HAProxy configuration, SELinux, firewalld, logging, Active Directory integration, hardening, testing and — perhaps most importantly — the problems I encountered along the way. Everything in this article uses deliberately generic hostnames, IP addresses and account names. Replace them with values appropriate for your own environment. What we’re building The finished system is a single Rocky Linux 10 VM running HAProxy. Each application has its own frontend IP address and its own backend pool. HAProxy operates in TCP mode, so the encrypted HTTPS traffic is passed through without HAProxy terminating TLS. The certificates remain installed on the application servers. The basic design looks like this: The three application pools are: Pool Frontend Backends Production app 10.0.3.10:443 app-prod-01 (10.0.0.108), app-prod-02 (10.0.0.109) Test / API 10.0.3.11:443 app-test-01 (10.0.0.115), app-test-02 (10.0.0.124) DMZ web 10.0.16.251:443 web-dmz-01 (10.0.16.30), web-dmz-02 (10.0.16.31) Placeholder values Throughout this article I’ll use the following example values: Item Value Load balancer hostname lb01.corp.example.com Local fallback account localadmin AD domain corp.example.com Internal network 10.0.0.0/22 Internal gateway 10.0.3.254 DNS/NTP 10.0.0.11, 10.0.0.10 DMZ network 10.0.16.0/24 Admin workstation subnet 10.0.52.0/24 These are examples only. Don’t copy them into a production environment without adapting them to your own network. Why use TLS passthrough? There are two common ways of putting HAProxy in front of an HTTPS application. The first is TLS termination. HAProxy receives the HTTPS connection, decrypts it and then establishes another connection to the backend. The second is TLS passthrough. With passthrough, HAProxy doesn’t need to know anything about the application’s certificates. It operates at Layer 4 and simply proxies the TCP connection. For this particular deployment, TLS passthrough made sense for several reasons. No certificates on the load balancer The certificates remain on the application servers. That means there is another machine that doesn’t need certificate renewal, private-key protection or certificate deployment. Very low resource requirements HAProxy isn’t performing TLS encryption and decryption for client connections. It’s primarily moving TCP traffic between sockets. This makes it possible to run the load balancer on a very small VM. The downside: source IP visibility There is an important trade-off. From the backend server’s perspective, the TCP connection originates from the HAProxy server rather than directly from the client. HAProxy knows the original client address and can record it in its own logs, but the backend application won’t automatically see the client’s real source IP. If the backend needs that information, there are alternatives such as the PROXY protocol, provided the backend supports it, or terminating TLS on HAProxy instead. VM sizing The VM I used was deliberately small: For this type of workload, there’s little benefit in throwing a large amount of hardware at HAProxy. In my testing, HAProxy itself used only around 13 MB of RAM. Obviously, real resource requirements depend on connection counts, traffic levels, logging and configuration. Once you’re dealing with very large numbers of concurrent connections, memory and file descriptors become increasingly important, while network throughput can become the limiting factor. For this type of deployment, however, adding a second load balancer for availability is much more useful than simply making the first VM larger. One important virtualisation consideration Rocky Linux 10 and other RHEL 10-based distributions have newer x86-64 CPU requirements than some older Linux releases. If you’re installing the VM on an older hypervisor or with a deliberately old virtual CPU model, the installer may complain about unsupported CPU features. If that happens, expose a newer CPU model to the VM. On VMware, using the host CPU where appropriate is one option. Step 1 — Install Rocky Linux 10 Install Rocky Linux 10 using the Minimal Install profile. The goal here is to keep the server small. There is no reason to install a graphical desktop or a collection of applications that the load balancer doesn’t need. Once the operating system is installed, install the packages required for HAProxy and administration: If you’re not running VMware, open-vm-tools isn’t required. Enable the services: Check the HAProxy version: The build documented here used HAProxy 3.0.5 from AppStream. Your version may differ depending on the Rocky Linux repositories available at the time you build the server. Step 2 — Configure the network This server has two network interfaces: The internal interface carries the normal server traffic and hosts the production and test frontend addresses. The DMZ interface carries the DMZ frontend. The important thing here is that the DMZ interface must not become a second default route. Internal interface In this example, ens33 has two IP addresses: Configure the NetworkManager connection: Check that both addresses are actually present: Check the address before using it Before assigning an additional address to a server, make sure another device isn’t already using it. For example: No response doesn’t guarantee an address is unused, but it is a useful first check. Also check your DHCP scopes and IP address management system. An address that doesn’t answer an ARP request today can still be part of a DHCP scope and become a problem later. Configure the DMZ interface The second interface in this example is ens35. The DMZ network is:

Building a Minimal HAProxy Load Balancer on Rocky Linux 10 Read More »
Home Lab Monitoring with a Raspberry Pi and Check_MK

Affiliate Disclosure: This post contains Amazon affiliate links. If you purchase a product through one of these links, I may earn a small commission at no additional cost to you. I only recommend products that I have personally used or believe are worth considering. My server rack doesn’t have a cooling solution like a data centre does. That isn’t practical in a home lab, but I still need to be conscious of temperature. Summers in England can bring scorching heat and winters can get very cold, and I want to be alerted when something is wrong before my servers crash. I also want to keep an eye on the power the rack uses, especially with electricity costing what it does now. I’ve used Check_MK to monitor my lab for years, and it’s already set up to email me alerts. So rather than build a separate system, this project feeds temperature, humidity and power readings from a Raspberry Pi into Check_MK, where I can set warning and critical thresholds like any other service. By the end you’ll have: Parts list The links in this list are Amazon affiliate links (see the disclosure at the top of the article). How it works Only two small services touch hardware: one reads the DHT22, one receives the radio messages from the power adapter. Each writes its latest reading to a tiny text file. Everything else, the display and the Check_MK agent plugin, just reads those files. That keeps the pieces independent, and it means two programs never fight over the same sensor. A few design decisions worth explaining: Building the unit The order of the build matters, because of how the Pi-mote fits. Fit the Pi-mote first The Pi-mote is a HAT: a board that plugs onto the Pi’s 40-pin GPIO header and sits over the top of it. I fitted it first. It covers pins 1 to 26 of the header, and every pin in the wiring table below (3.3V, GND, GPIO 4, SDA and SCL) is among them, so there was nowhere to push jumper leads onto those pins for the DHT22 or the display. Connecting the DHT22 and the display Because those pins are covered, I soldered the wires for the DHT22 and for the display straight onto the Pi-mote, at the pins that carry the connections we need. The pin numbers below are the usual ones for a Raspberry Pi 40-pin header. Check them against a pinout for your own board. The Pi-mote’s radio uses SPI and a few other pins of its own; in my build none of those clash with the connections below. Device Pin Header pin DHT22 VCC / + 3.3V (pin 1) DHT22 OUT / data GPIO 4 (pin 7) DHT22 GND / – GND (pin 9) OLED VDD 3.3V (pin 17) OLED GND GND (pin 14) OLED SDA GPIO 2 / SDA (pin 3) OLED SCK GPIO 3 / SCL (pin 5) Power the DHT22 from 3.3V, not 5V. With a 5V supply its data line can rise above what the Pi’s GPIO pins tolerate. A few practical tips for soldering onto a board that’s already fitted: Making room for the antenna The Pi-mote has a copper coil, its antenna, which sticks up from the board. A normal case lid would press down on it. So I cut a long rectangular opening in the lid with a Dremel rotary tool. The coil sits in the opening, and the lid closes properly without touching it. Take your time with this part. Mark the opening from the coil’s actual position and size, make the cut a little larger than the coil, and smooth the edges so they can’t catch the wires or the antenna. If you use a rotary tool as I did, clamp the lid down, wear eye protection, and use a cutting disc at a low speed, because plastic melts if the tool runs too fast. Finish the edges with a file or a sanding bit. Then close the lid and check nothing is pressing on the coil. The coil is how the unit hears the power adapter, so you don’t want it squashed or bent. Sensor placement: a lesson learned I first attached the DHT22 straight onto the Raspberry Pi case. It read about 25 °C while the room was 20 °C. The Pi itself was running at about 42 °C, and its heat was adding roughly 5 °C to the sensor’s reading, so my sensor was partly measuring the Pi, not the room. Humidity was affected as well. Relative humidity depends on temperature, so air that is warmed reads drier than it really is, which means a temperature error carries over into the humidity reading. Five degrees might not sound like much, but alert thresholds depend on it. With a warning level at 30 °C, an error of 5 °C uses up a large part of your margin. It isn’t a fixed offset you can simply subtract either, because the Pi’s temperature changes with how hard it’s working. So put the sensor on a cable and place it where it measures what matters, which is the air your servers breathe. That usually means the intake side of the rack at about mid-height. Avoid the exhaust, the top of a piece of equipment, and anywhere near a power supply or the Pi. The DHT22 uses a single data wire, so a few practical notes on the cable: If a longer cable causes read errors, the reader service logs a warning (shown later in the troubleshooting section) and Check_MK raises a stale-data alert. I moved the sensor off the case and onto its own extension cable, away from the unit. The only change to the build was the cable: no software changes were needed. Preparing the Pi With the hardware built, it’s time for the software. Install Raspberry Pi OS, then enable the interfaces we need. The OLED uses I2C and the Pi-mote’s radio uses SPI: Install the supporting packages and the libraries the scripts

Home Lab Monitoring with a Raspberry Pi and Check_MK Read More »

Building a Paper-Trading Bot, Part 3: A Live Dashboard on Apache

This is Part 3 of a 3-part series. Part 1 tells the story of building this bot and what went wrong along the way. Part 2 is the step-by-step setup and full working code for the bot itself — read that first if you don’t have the base project running yet, since this post builds directly on top of it. By the end of Part 2, the bot is trading and logging every trade and daily equity snapshot to CSV files. That’s fine if you’re comfortable reading raw CSVs over SSH, but it gets old fast. This post adds a proper dashboard: a self-updating web page showing your strategy’s performance against simple buy-and-hold, served over Apache on the same Linux box the bot is already running on. What we’re building No server-side app, no database — Apache just serves whatever static HTML file was most recently generated. Simple to set up, simple to reason about, nothing to keep running besides the bot itself. Prerequisites Step 1: A console report script (optional but useful) Before building the HTML version, here’s a simpler console-only report script — useful for a quick check over SSH without needing a browser at all: Save this as report.py in your project directory. Run it anytime: It prints your total return, a buy-and-hold comparison, max drawdown, recent trades, and saves a matplotlib chart (equity_curve_ACN.png) you can pull off the server if you want a quick visual without setting up the full dashboard. Step 2: The HTML dashboard generator This is the main piece — a script that builds a complete, self-contained HTML report from your log files. It’s a long file because the HTML/CSS/JavaScript for the chart is embedded directly in the Python script as a template, which keeps the whole dashboard to a single generated file with no separate assets to manage. Save this as generate_html_report.py. A few things worth understanding about what it does: Generate your first report: This creates a web/ACN/index.html file inside your project directory. Open it locally first (copy it to your own machine, or just cat it) to confirm it looks right before wiring up Apache. Step 3: Point Apache at the report The simplest approach is an Apache Alias, which maps a URL path directly to your project’s web/ folder without needing to copy files into /var/www/html or mess with permissions there. Create a new Apache config file: Replace YOUR_USERNAME with your actual Linux username. Then enable the config and reload Apache: Visit http://your-server-ip/tradingbot/ACN/ in a browser — you should see the dashboard. If you get a 403 Forbidden error This is the most common snag, and it’s almost always permissions. Apache runs as the www-data user, and it needs traversal permission on every directory in the path to your file — not just the final folder. Home directories are often locked down by default, which blocks www-data even though the Apache config itself is correct. Check the whole permission chain: If any directory in that list is missing execute (x) permission for “others,” grant just enough to allow traversal — not full access: This only allows Apache to pass through those directories to reach the specific file — it doesn’t let it list or read anything else inside them. Step 4: Keep the report fresh with cron Right now the dashboard only shows whatever was true the moment you ran the generator script. Set up a cron job to regenerate it automatically: Add a line to regenerate the report every 15 minutes (matching the bot’s default polling interval): Two details that matter here: Step 5: Running more than one symbol If you’re paper-trading multiple symbols (see Part 2 for running two main.py instances at once), generate a report per symbol into its own subfolder: With the Apache Alias from Step 3, these become reachable at /tradingbot/ACN/ and /tradingbot/SPY/ respectively. Add a second cron line for the second symbol, same pattern as Step 4. A note on security This setup has no authentication — anyone who can reach the URL can see your (paper) trading performance. That’s a reasonable trade-off on a private home network, but not something to expose directly to the public internet. If you need external access, put it behind a reverse proxy with basic auth, or at minimum restrict by IP address directly in the Apache config: Replace the example IP range with whatever network you actually trust. Wrapping up the series That’s the full build: a modular trading bot with a tested strategy and real risk management (Part 2), built on the lessons from actually running it and hitting real bugs (Part 1), now with a live dashboard to watch it work (this post). The whole project — bot, backtester, and dashboard — is maybe 1,500 lines of Python, and every part of it earned its place by something that broke during actual use, not by anticipating problems in advance. That’s probably the biggest lesson of the whole series: build the smallest version that works, run it for real, and let what actually breaks tell you what to build next.

Building a Paper-Trading Bot, Part 3: A Live Dashboard on Apache Read More »

Building a Paper-Trading Bot, Part 2: Full Setup and Code on Linux

This is Part 2 of a 3-part series. Part 1 is the story of what went wrong and what I learned building this — worth reading first for context. This post is the step-by-step build: Linux setup and the complete working code. Part 3 covers adding a live performance dashboard served over Apache. This is a complete walkthrough for building a paper-trading bot in Python using the Alpaca API, running on a Linux server. By the end you’ll have a bot that pulls market data, generates buy/sell signals from a trend-following strategy, manages risk with a volatility-scaled stop-loss, executes paper trades automatically, and logs everything for review. Everything below is real, working code — this is the actual project I run in production (well, paper-production) on my own Ubuntu server. What you’ll end up with Prerequisites Step 1: Get free Alpaca paper trading API keys Paper trading uses simulated money against real market data, so you can test everything safely before ever considering real funds. Step 2: Set up the project directory and virtual environment That last command activates the virtual environment — you should see (venv) appear at the start of your terminal prompt. You’ll need to run source venv/bin/activate again every time you open a new terminal session to work on this project; it only applies to the current shell. Step 3: Install dependencies Create a requirements.txt file: Then install: Step 4: Store your API keys securely Create a .env file in the project root: Replace the placeholders with the keys from Step 1. Never commit this file to version control — if you’re using git, add .env to your .gitignore. Step 5: Build the project, file by file Here’s the full project structure we’re building: config.py — central settings Everything the rest of the project needs is configured here: API keys, strategy parameters, and risk settings. A few of the defaults worth understanding before you change them: data_feed.py — pulling market data This wraps Alpaca’s data API so the rest of the code doesn’t need to know the API details. strategy.py — the actual trading logic This is the heart of the bot: turning price data into a BUY, SELL, or HOLD decision. A quick note on the design here, since it’s easy to get subtly wrong: signals are evaluated as a current state (is the short average above the long average right now, and does ADX confirm a trend right now) rather than only firing on the exact bar a crossover happens. An earlier version of this logic only fired on the crossing bar itself — which sounds equivalent but isn’t: if ADX takes a few days to confirm a trend after the crossover already happened, an event-based check misses the entry entirely, since the “crossing” moment has already passed by the time confirmation arrives. Checking the state fresh on every bar avoids that. risk.py — position sizing and stop-loss The stop-loss uses ATR (Average True Range) instead of a flat percentage. Here’s why that matters: a flat 2% stop sounds reasonable until you apply it to a volatile stock — a 2% intraday swing can be completely normal noise for a volatile name, so a flat stop just gets you shaken out repeatedly by nothing. Scaling the stop to each symbol’s own recent volatility means a calm stock gets a tight stop and a volatile one gets appropriately more room. executor.py — talking to Alpaca Two things worth calling out: trade_logger.py — recording everything This logs to per-symbol CSV files (trade_log_ACN.csv, equity_log_SPY.csv, etc.) so you can run multiple symbols from the same project directory without their logs overwriting each other. Step 6: Backtest before running anything live This is the step I’d encourage you not to skip, whatever strategy you end up using. Here’s the backtesting script: backtest.py Run it like this: The most important line in that output is the buy-and-hold comparison. A strategy can show a positive return and still be a bad idea — the only way to know is to compare it against what you’d have gotten just buying and holding the same stock over the same period. Don’t skip this comparison; it’s the single most useful sanity check in the whole project. You can also tune the strategy’s parameters directly from the command line without touching the code: Step 7: Run the live paper-trading loop Once you’re comfortable with the backtest results, here’s the live trading script: main.py Run it with: This polls every 15 minutes by default, checks the strategy’s signal, and submits paper orders through Alpaca when conditions are met. Each cycle prints the current indicator values (moving averages, ADX, current position) so you can watch it work in real time instead of guessing what it’s doing. Step 8: Keep it running with tmux SSH sessions die, laptops sleep — you don’t want the bot to stop just because your terminal disconnected. tmux solves this: Detach with Ctrl+B then D (press and release Ctrl+B, then press D separately — it’s a two-step sequence, not a single chord). The bot keeps running in the background. Reattach anytime with: Step 9: Check in on it periodically A few habits worth building once this is running unattended: A couple of hard-earned lessons Don’t gate your stop-loss on the same trend filter as your entry. I initially removed the ADX confirmation from the exit condition, reasoning the ATR stop already handled downside risk. Backtesting showed this let the strategy bail on ordinary pullbacks within an otherwise healthy trend, then re-buy shortly after — generating more whipsaw losses than it prevented. Requiring trend confirmation on both entry and exit, symmetrically, fixed it. Always check for pending orders, not just filled positions, before submitting a new one. This is the bug that cost me fourteen unintended paper trades in one morning. If an order is submitted while the market is closed, it sits queued rather than executing — and a polling loop that only checks “do I already hold a position” has no

Building a Paper-Trading Bot, Part 2: Full Setup and Code on Linux Read More »

Building a Paper-Trading Bot, Part 1: What I Learned From Getting It Wrong Three Times

This is Part 1 of a 3-part series on building a paper-trading bot from scratch. This post is the story — what I built and what went wrong along the way. Part 2 is a step-by-step tutorial with the full working code if you want to build it yourself. Part 3 covers adding a live performance dashboard served over Apache. I set out to build a trading bot. I ended up learning more about testing discipline, benchmark comparisons, and the subtle ways “correct-looking” code can still be wrong than I did about trading itself. This is the story of that build — the architecture, the backtests that punctured my assumptions, and two live bugs that only showed up once real automation was running unattended. If you’re thinking about building something similar, I’d rather show you where it actually went sideways than pretend it was smooth from commit one. The starting point The goal was modest on purpose: get a Python bot paper-trading on Alpaca, with a strategy simple enough to reason about — a moving-average crossover. Before writing a line of strategy logic, I laid out the pipeline as separate, swappable pieces: Keeping these separate turned out to matter a lot more than I expected. Every bug I hit later was isolated to one module, and I could reason about (and fix) each one without touching the others. The first version of the strategy was a plain SMA crossover: buy when a 20-day moving average crosses above a 50-day average, sell on the reverse. Dead simple, and a reasonable scaffold to prove the plumbing worked end to end. Backtest #1: humbled by buy-and-hold The first backtest ran fine — positive return, plausible-looking trades. It felt like a win right up until I added one more line of output: what would buy-and-hold have returned over the same period? That single comparison changed everything. On AAPL over a 730-day window, the strategy returned about 25%. Buy-and-hold returned nearly 47%. The strategy wasn’t just “okay” — it was leaving almost half its potential return on the table, entirely because it sat in cash during a strong bull run, waiting for confirmation signals that a buy-and-hold investor never needed. Lesson: a backtest without a benchmark isn’t really a backtest — it’s just a number. Positive returns feel good in isolation, but “good” is only meaningful relative to the simplest alternative: doing nothing. Adding a trend filter — and testing it honestly The obvious next step was gating the crossover on trend strength, using ADX (Average Directional Index) — only trust a crossover if ADX confirms the market is actually trending, not just noisy. That cut down on whipsaw trades in choppy periods. But here’s the thing about a filter like this: it has a real cost as well as a real benefit, and you only see the cost by testing it somewhere it’s supposed to hurt. So instead of only testing on one stock, I ran the same strategy across four very different regimes: The pattern that emerged was completely coherent, and completely different from what a single-symbol test would have shown: the strategy underperformed buy-and-hold by 20-30 percentage points on AAPL and SPY (the cost of waiting for confirmation in a market that just kept going up), but beat buy-and-hold by over 25 percentage points on ACN — it correctly stepped aside during the worst of a real decline. That’s not a strategy that “works” or “doesn’t work.” It’s a strategy with a specific, identifiable regime it’s good for. Knowing that is worth infinitely more than a single aggregate number from one stock. The stop-loss that made things worse Position risk was still an open problem — a naive flat 2% stop-loss sounded reasonable on paper. It was not reasonable in practice. Backtesting it on COIN revealed why: nine stop-loss exits in under a year, several just days apart. A 2% move is ordinary daily noise for a stock as volatile as COIN — the stop wasn’t protecting against real reversals, it was getting shredded by the stock’s normal breathing room, forcing repeated re-entries at worse prices each time. The fix was to scale the stop distance to each symbol’s own volatility using ATR (Average True Range) instead of a flat percentage — entry_price – (2.5 × ATR at entry). A volatile stock naturally gets a wider stop; a calm one gets a tighter one. Re-running the same COIN backtest after the change: stop-loss exits dropped from nine to two, and the damage from each was cut by more than half. Lesson: risk parameters that “feel” reasonable in isolation can be actively harmful without accounting for the asset’s own behavior. Test the thing you added, not just the thing you started with. Going live surfaced a bug backtesting couldn’t catch Backtesting works because you’re replaying finalized, settled data. Live trading exposed a class of bug that simply doesn’t exist in that world: timing. The original signal logic only fired a BUY on the exact bar a crossover happened, gated by whether ADX confirmed a trend on that same bar. In backtesting, this looked fine. Live, it quietly broke: ADX often takes a few days to climb above the trend threshold after a price move starts. If the crossover happened while ADX was still catching up, the strategy correctly held off — and then never revisited the decision, because the “crossing” moment had already passed by the time ADX confirmed anything. I only caught this because I was watching the live indicator values directly and noticed SMA20 sitting comfortably above SMA50, with ADX freshly past the trend threshold — every condition for a buy, and yet nothing fired. The fix was switching from event-based signals (“did the cross happen on this exact bar?”) to state-based signals (“is the market currently in a qualifying state?”) — evaluated fresh every cycle instead of only at the moment of crossing. Re-running backtests after the fix produced a nuance worth sitting with: the fix helped one symbol

Building a Paper-Trading Bot, Part 1: What I Learned From Getting It Wrong Three Times Read More »

Ubuntu 14.04: How to Extend Disk Space on a Physical or Logical Volume

If you have inherited an old Ubuntu 14.04 server or virtual machine and suddenly find that the filesystem is running out of disk space, extending the storage can be a little confusing. This guide walks through the process of increasing disk space on an Ubuntu 14.04 server using LVM, including the steps required after increasing the virtual disk in VMware. Although Ubuntu 14.04 is now a legacy operating system, these systems still exist in production, lab environments and old applications that cannot easily be upgraded. Important: Ubuntu 14.04 reached end of standard support in 2019. Only use this guide for systems that genuinely need to remain on this legacy release. Always take a backup or snapshot before making partition or filesystem changes. The basic process When increasing the storage of an Ubuntu virtual machine, there are several separate layers involved: Depending on how the server is configured, you may need to extend one or more of these layers. For an LVM-based server, the usual process is: 1. Check the current disk layout Before making any changes, find out how the server is currently configured. Start with: This shows the filesystems and how much space they are currently using. For example: In this example, the root filesystem is only 20 GB and is almost full. Next, look at the disks and partitions: You can also use: And, because this is an LVM system, check the physical volumes, volume groups and logical volumes: These commands are extremely useful because they show where the available space actually exists. 2. Increase the virtual disk in VMware If this is a VMware virtual machine, first increase the size of the virtual hard disk in vCenter or the VMware management interface. For example, you might increase: At this point VMware knows about the additional 40 GB, but Ubuntu may still be reporting the original disk size. Depending on the Ubuntu/kernel configuration, a reboot may be required. For a legacy Ubuntu 14.04 server, I would generally recommend scheduling a reboot rather than relying on a storage rescan if the system is not known to support the required hot-rescan workflow. After the reboot, check: You should now see the larger disk. For example: 3. Identify the available space Run: You may see something similar to: If the disk is now 100 GB but the final partition ends at 60 GB, the remaining space is currently unallocated. For example: The exact layout will vary between servers, so do not blindly copy partition numbers from this example. 4. Create a partition using the new space If the additional disk space is outside the existing LVM partition, create a new partition using the available space. On Ubuntu 14.04, fdisk is commonly available: Inside fdisk, use: to create a new partition. Select the default start and end sectors if you want to use all of the available space. Then change the partition type to Linux LVM: and select: Finally, review the changes with: If everything looks correct, write the changes: Be careful fdisk modifies the partition table. Selecting the wrong disk or deleting an existing partition can cause data loss. Always verify the device name with: before making changes. 5. Check that Linux sees the new partition Run: You should now see something similar to: If the new partition does not appear immediately, try: Then check again: On some older systems, a reboot may be required before the kernel recognises the updated partition table. 6. Create an LVM Physical Volume If the new partition is going to be added to LVM, initialise it as a Physical Volume: You should see a message similar to: Confirm it with: You should now see /dev/sda3 listed as an LVM Physical Volume. 7. Add the Physical Volume to the Volume Group Next, identify the existing Volume Group: For example: In this example, the Volume Group is: Add the new Physical Volume: Check the result: The available free space should now have increased. 8. Extend the Logical Volume Now identify the Logical Volume: You might see: The Logical Volume path would therefore be: You can extend it by a specific amount. For example, to add 20 GB: Or, if you want to allocate all remaining free space in the Volume Group: The + is important. For example: means add 20 GB. Without the +, the value represents the new total size of the Logical Volume rather than the amount to add. Ubuntu’s LVM documentation also documents the +100%FREE approach for allocating the remaining free extents. 9. Extend the filesystem At this point the Logical Volume has been increased, but the filesystem may still be the original size. Check: If the filesystem has not grown, it needs to be resized. For an ext3/ext4 filesystem, use: You should see output indicating that the filesystem has been resized. Check again: The additional space should now be available. 10. A simpler LVM approach On versions of LVM that support it, lvextend can resize the Logical Volume and filesystem together using -r: The -r option tells LVM to resize the underlying filesystem as part of the operation. The Xenial/Ubuntu 16.04 lvextend documentation confirms support for –resizefs, although on an old Ubuntu 14.04 server I prefer the explicit two-step approach because it makes it much clearer what is happening. For a legacy server, I would therefore use: Extending an existing LVM partition instead The above example assumes that the additional disk space requires a new partition such as /dev/sda3. There is another common scenario. If you increased the size of a disk and the existing LVM partition itself now has additional space available, you may only need to resize the existing Physical Volume. For example: Then check: If the Volume Group now has additional free space, extend the Logical Volume: Then resize the filesystem: This distinction is important: Verify everything Once the resize is complete, check all the layers. Check the disk Check the Physical Volumes Check the Volume Group Check the Logical Volumes Check the filesystem For example, you should now

Ubuntu 14.04: How to Extend Disk Space on a Physical or Logical Volume Read More »

Create a New Ubuntu Disk Partition Using Parted

If you have added a new disk to an Ubuntu server, you can use parted to create a partition and then format it ready for use. This guide shows how to create a single GPT partition using the entire disk. Warning: Double-check the disk device before partitioning. The commands below will modify the selected disk and can destroy existing data. Identify the New Disk First, list the disks attached to the server: For example: In this example, /dev/sdb is the new 100GB disk. Create the Partition Start parted against the new disk: Create a GPT partition table: Set the unit to GB: Create a single partition using the available space: You can then verify the partition: When everything looks correct, exit: The new partition should now be available as: Format the Partition For a typical Ubuntu data disk, I would recommend ext4: If you specifically need FAT32 instead: The partition is now created and formatted. The next step is to create a mount point and mount it, or add it to /etc/fstab if it needs to be mounted automatically after a reboot.

Create a New Ubuntu Disk Partition Using Parted Read More »